

Best Lipsync Models 2026: Picks by Job and Price
The best lipsync model depends on your input: Sync Lipsync 2.0 for footage, VEED Fabric 1.0 for a photo, HeyGen Avatar V for a presenter. Credits inside.
Dubbing Studio
One video, three languages
The same clip through Versely's dubbing pipeline: English original, then HeyGen lip-sync into French and Spanish with captions burned in.
The best lipsync model depends on what you start from. To re-sync filmed footage to new audio, use Sync Lipsync 2.0, or its Pro version for close-ups; VEED Lipsync is the low-cost option. To make a still photo talk, use VEED Fabric 1.0 or Kling Avatar. For a ready-made presenter, use HeyGen Avatar V or VEED Avatars.
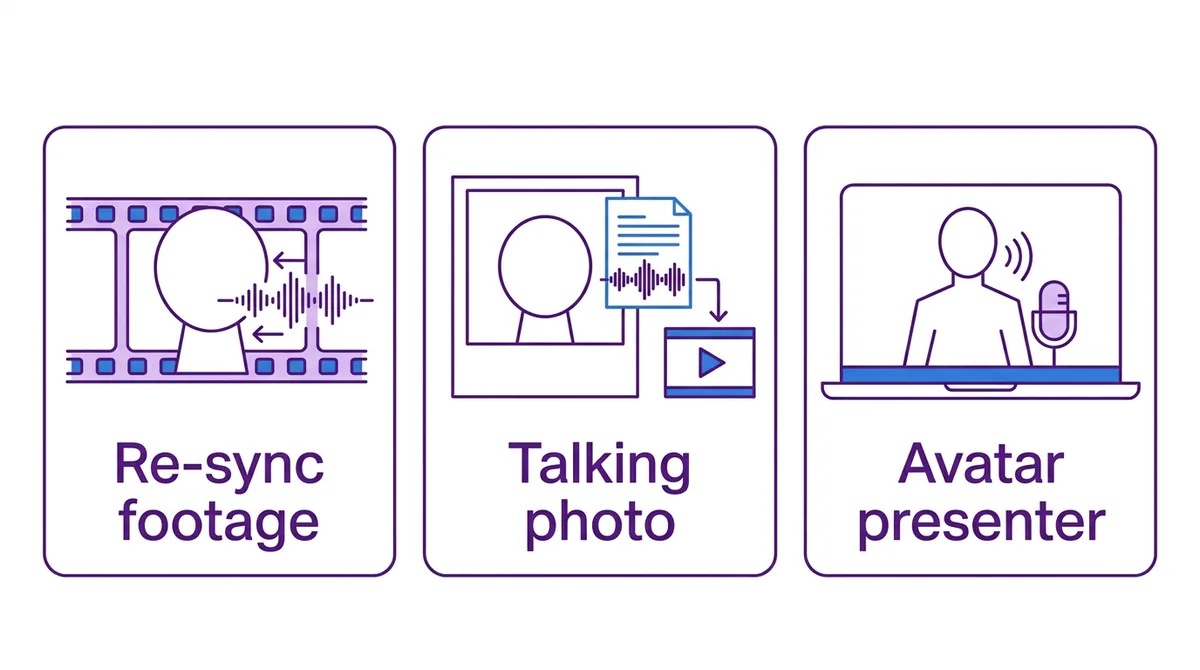
The three lipsync jobs
- Re-sync footage. You have video of someone talking and need their mouth to match different audio: a dub, a corrected line, a new voiceover.
- Talking photo. You have one still image and an audio track or script, and need a speaking video with head motion.
- Avatar presenter. You need a presenter who delivers scripts on demand, without filming anyone.
Pick the job first. A re-sync model given a still photo has nothing to work with, and a talking-photo model throws away the performance in footage you already shot.
Key facts: lipsync models on Versely
| Model | Job | From | Per second |
|---|---|---|---|
| Sync Lipsync 2.0 | Re-sync | 20 credits | 4 (Pro: 7) |
| Sync React 1 | Re-sync + emotion | 67 credits | 14 |
| VEED Lipsync | Re-sync | 3 credits | 1 |
| Kling Lipsync | Re-sync | 6 credits | 6 per 5 s |
| VEED Fabric 1.0 | Talking photo | 32 credits | 7 (HD: 12) |
| Kling Avatar Pro | Talking photo | 46 credits | 10 (Std: 5) |
| HeyGen Image to Video | Talking photo | 40 credits | 8 |
| HeyGen Avatar V | Presenter | 40 credits | 8 |
| VEED Avatars | Presenter | 3 credits | 1 |
"From" is the smallest job each model page shows on 29 October 2026; longer clips cost the per-second rate. Sync Lipsync 2.0 Pro starts at 34 credits and Kling Avatar Standard at 23; both sit on the same pages as their siblings.
Re-syncing footage you already shot
Sync Lipsync 2.0 is the default for real footage. Sync Labs describes lipsync-2 as able to "preserve the unique speaking style of every speaker", so the new mouth movement looks like that person talking rather than a generic mouth. The Pro row runs lipsync-2-pro, which Sync describes as adding diffusion-based super resolution, with better detail on beards, teeth and facial features. Use Pro for close-ups and paid placements, where teeth and lips fill the frame.
One limit to plan around, from Sync's own documentation: both models need natural speaking motion in the input. They work in 2-second chunks, and where the speaker is still or silent, they won't add lip movement even if the new audio has speech there. Shoot or pick takes where the speaker talks throughout.
Sync React 1 goes beyond the mouth. It re-performs the face to the new audio and, on Versely, takes an emotion setting (happy, angry, sad, neutral, disgusted or surprised) and a mode for lips only, the face or the whole head. Use it when the new line needs a different delivery, not just new words.
VEED Lipsync is the volume option: video plus audio in, a synced clip out, at 1 credit a second. It suits course libraries, podcast clips and batches of product videos going to several markets, where medium shots hide small sync differences.
Kling Lipsync syncs a speaker's mouth in an existing video to new audio. fal lists it for dubbing, voice actors and localization. Versely bills it per 5 seconds, from 6 to 12 credits a clip, which makes it a cheap way to fix a short line.
Making a still photo talk
VEED Fabric 1.0 turns one image and an audio track into a talking video with head motion. fal's page for it lists 720p output and commercial use. The Fabric 1.0 Text variant takes a script instead of audio and generates the voice for you. It needs no footage and no training, so it suits UGC-style personas, covered in Best AI Models for UGC and Avatar Videos.
Kling Avatar animates an image from audio, and fal's listing for the v2 model names realistic humans as well as cartoon and stylised characters. Pick it when your "photo" is an illustration or a mascot. Standard is 5 credits a second and Pro 10.
HeyGen Image to Video runs HeyGen's photo avatar: upload a photo, choose a voice and get a lip-synced talking video. It's the HeyGen route when you don't have footage.
A presenter without a shoot
HeyGen Avatar V is what HeyGen calls its most advanced avatar model, built around keeping one identity consistent across angles and scenes. On Versely it runs HeyGen's Avatar V presenters from a script or audio. In HeyGen's own app, Avatar V can also make a digital twin of you from a 15-second webcam recording.
VEED Avatars removes even the photo: pick one of VEED's stock presenters, type the script and get a synced clip at 1 credit a second. A VEED Avatar Audio row on the same page drives those presenters from your own voice track instead. You get the same face across a hundred clips with no rights questions, at the cost of distinctiveness, since stock faces belong to nobody's brand.
The dubbing pipeline
The most useful lipsync workflow is multilingual. Translate and voice the script first, ideally in a cloned voice of the original speaker, then re-sync the mouth to the new language, then caption each version.
- Dub first, sync second. Syncing to a scratch translation and then re-dubbing means paying for the sync twice.
- Watch for length changes. A translation can run longer or shorter than the original line. Time-fit the audio before you sync, and check shots where the speaker's rhythm shows, such as walking or gesturing on a beat.
The voice half of the stack is in the voice cloning guide, the translation step runs in the AI dubbing tool, and the sync step runs in the AI lipsync tool.
Quality checklist before you publish
- Scrub to a "b", "m" or "p". The lips must fully close on those sounds. It's the fastest tell.
- Watch the jaw as well as the lips. Real speech moves both.
- Check the first word. If it smears, trim or pad the start of the audio and run it again.
- Look at the teeth in close-ups. Flickering or morphing teeth mean the shot needs the higher-detail model, such as Sync Lipsync 2.0 Pro.
- Play it muted. A good sync still looks like natural speech without sound.
Limits worth knowing
Profile shots, hands or microphones in front of the mouth, and partly hidden faces are hard for every re-sync model. Sync lists better handling of extreme angles and obstructions as a selling point of its newest model, sync-3, which Versely doesn't offer. Keep synced speakers facing the camera where you can. Singing is harder than speech: sustained vowels and pitch slides expose timing, so budget retries for music.
FAQ
What is the best lipsync model in 2026?
For re-syncing real footage, Sync Lipsync 2.0, with the Pro version for close-ups. For a talking photo, VEED Fabric 1.0, or Kling Avatar for illustrated characters. For a presenter without filming, HeyGen Avatar V. VEED Lipsync and VEED Avatars are the low-cost picks at 1 credit a second on Versely.
What is the difference between a lipsync model and a talking-avatar model?
A lipsync model changes the mouth in video that already exists, so the rest of the performance stays. A talking-avatar model builds the whole performance (head motion, expression, mouth) from a photo or a stock presenter plus audio.
Can lipsync models make a photo talk?
Yes, that's what VEED Fabric 1.0, Kling Avatar and HeyGen Image to Video do: one image plus audio, or a script with Fabric 1.0 Text, becomes a talking video. A clear, front-facing, well-lit photo gives the best result.
How much does AI lipsync cost on Versely?
From 3 credits for VEED Lipsync and VEED Avatars, at 1 credit a second. Sync Lipsync 2.0 starts at 20 credits (4 a second), and VEED Fabric 1.0 at 32. Each model page shows the full price range.
Should I use a stock avatar or my own face?
Stock avatars win on speed and on rights for volume content. Your own face, from a Fabric photo or a HeyGen twin, wins on recognition and trust for a series. More options are compared in Best lip sync API 2026 and Best AI lip-sync tools 2026.
Put a voice to a face in the AI lipsync tool: re-sync a clip or make a photo talk, on the web app or the iOS app.
Versely AI Weekly
New AI models, every Thursday.
The image, video, audio and LLM models released that week, what each is good for, and what's new on Versely.