

Best Text-to-Speech API in 2026: Pick by Constraint
Compare text-to-speech APIs on latency, price per 1,000 characters and languages: Cartesia, ElevenLabs and Deepgram, with prices checked 13 November 2026.
The best text-to-speech API in 2026 depends on one constraint you should name before you read another benchmark: latency, expressiveness, price, or deployment control. Cartesia Sonic 3.6 and ElevenLabs' Flash / Turbo models both claim first audio in under about 100 ms. ElevenLabs v4 and v3 lead on expressiveness and language coverage. Deepgram leads on price and on-prem deployment. Hume Octave 2 was the emotional-fidelity pick, but Hume set its TTS API to end on 13 November 2026, and that date has passed.
That's not a hedge — it's the actual shape of the market right now, and treating it as one horse race is how teams end up integrating the wrong API and re-platforming six months later. Prices and latency claims below were re-read from each vendor's own pages on 13 November 2026.
The short answer
- Need first audio in roughly 100 ms or less (voice agents, live dubbing, anything with a human waiting on the other end) — Cartesia Sonic 3.6 (under 90 ms claimed) or ElevenLabs Flash / Turbo (about 75 ms claimed). Those are vendor figures, measured differently, so test on your own stack.
- Need the broadest language coverage and the most expressive delivery — ElevenLabs v4 (90+ languages) or v3 (70+ languages).
- Need a voice that carries emotional nuance (character work, sensitive support contexts, audiobook performance) — ElevenLabs v4 or v3 with audio tags. Hume Octave 2 was built for this, but its API reached its end date on 13 November 2026.
- Need on-prem or VPC deployment — Deepgram, which offers self-hosted containers to Enterprise customers.
- Need the cheapest API that's still genuinely usable — Deepgram Aura-1 ($0.015) and Aura-2 ($0.030) per 1,000 characters, then ElevenLabs Flash / Turbo ($0.04), then Cartesia Sonic 3.6 on its Pro plan ($0.05).
If you're producing finished video or audio content rather than building your own app, the calculus changes — more on that below.
The four APIs, what they actually are
Cartesia Sonic 3.6 — the latency and volume pick
Cartesia's Sonic page claims first audio in under 90 ms across 44 languages from one model, and its docs say Sonic 3.6 reads emotional context from the transcript without SSML tags. Cartesia's Pro plan is $5 a month for 100,000 credits at one credit per character, which is $0.05 per 1,000 credits, falling to about $0.037 on the $299 Scale plan (Cartesia pricing). Sonic 3.6 is Cartesia's newest model; there is no "Sonic 4".
ElevenLabs v4 and v3 — the expressiveness and coverage pick
ElevenLabs' API pricing page lists v4 as "our fastest and most emotive voice model", with audio tags and 90+ languages, and v4 Turbo as its real-time version at about 100 ms. v3 has 70+ languages, multi-speaker dialogue and a 5,000-character limit. Flash / Turbo has about 75 ms latency and 32 languages. List prices per 1,000 characters are $0.08 for v4 (a launch promotion of $0.022 ran to 12 October 2026), $0.04 for v4 Turbo, $0.08 for v3 and $0.04 for Flash / Turbo. Paid plans are Starter $6, Creator $22 and Pro $99 a month, and the page cites a library of 17,000+ voices. That costs more per character than Cartesia or Deepgram at the top end, and the trade is legitimate: voice library depth and language reach mean you are less likely to run out of options for a specific brand or character.
Deepgram Aura — the cheap and on-prem pick
Deepgram publishes pay-as-you-go text-to-speech rates of $0.015 per 1,000 characters for Aura-1, $0.030 for Aura-2 and $0.045 for Flux TTS. On its Growth plan the two Aura rates are 10% lower ($0.0135 and $0.027), and Flux TTS stays at $0.045 (Deepgram pricing). For Enterprise customers with data-sovereignty or security requirements it also offers self-hosted containers that run in your own VPC or on-premise hardware (NVIDIA GPUs required). That makes it the option for teams that need deployment control as much as a low per-character rate.
Hume Octave 2: API ended 13 November 2026
Hume's pitch was emotional fidelity: voices that carry believable feeling rather than a technically clean but affectively neutral read. On 2 October 2026 Hume announced that it was sunsetting its TTS and EVI APIs, with access ending on 13 November 2026 at 12:01 a.m. EST and account data permanently deleted afterwards, in the notice Developers Digest quotes. That date has passed, and on 13 November Hume's old voice docs redirected to its Audio Decisions product. The notice pointed to Hume's Real World VoiceEQ benchmark for alternatives, and what replaces Hume Octave 2 lists the closest voices from it. Before the docs came down, Hume's acting-instructions page said the plain-English description field was available for Octave 1 only, with Octave 2 support "coming soon". If your use case has emotional weight, use ElevenLabs v4 or v3, or on Versely Gemini 3.8 Flash TTS and Inworld TTS 2, which take natural-language style direction.
The comparison table
| Provider | First-audio claim | List price (per 1,000 characters) | Languages | Best for |
|---|---|---|---|---|
| Cartesia Sonic 3.6 | Under 90 ms (Cartesia) | $0.05 on Pro, about $0.037 on Scale | 44 | Real-time agents, live dubbing, volume batch |
| ElevenLabs v4 | About 100 ms for v4 Turbo (ElevenLabs) | $0.08 ($0.04 for v4 Turbo) | 90+ | Expressiveness, localization |
| ElevenLabs v3 | About 280 ms for v3 Conversational (ElevenLabs) | $0.08 | 70+ | Dramatic, emotionally rich reads |
| ElevenLabs Flash / Turbo | About 75 ms (ElevenLabs) | $0.04 | 32 | Low latency at a low price |
| Deepgram Aura-2 | Not compared here | $0.030 | Not compared here | Price, on-prem and VPC deployment |
| Hume Octave 2 | Not compared here | API ended 13 November 2026 | Not compared here | No longer available |
Read the "not compared here" cells as a limit of this article, not a gap in the vendor. Latency figures are each vendor's own claim and are not measured the same way, so a 75 ms against 90 ms gap on paper does not decide anything.
Pick by constraint, not by leaderboard
Run this in order, and stop at the first constraint that's non-negotiable for your project:
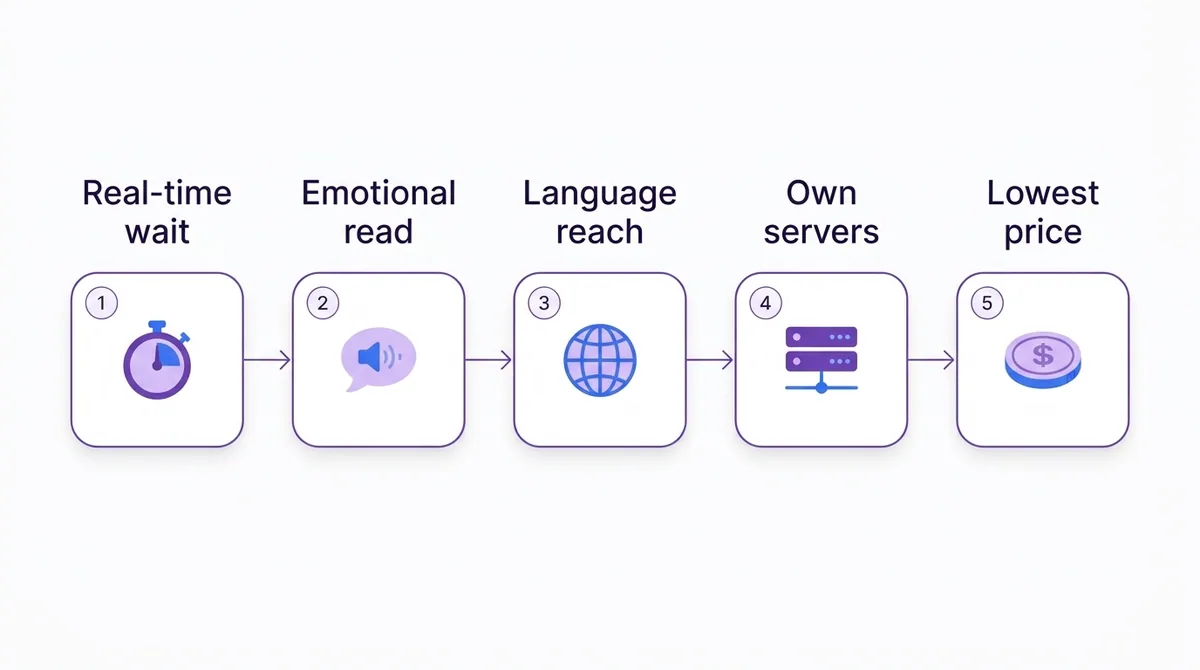
- Does a human wait on the response in real time? (voice agent, live call, live-dubbed stream) → Cartesia Sonic 3.6 or ElevenLabs Flash / Turbo, tested on your own stack with your own network path.
- Does the read need to sound genuinely emotionally right, not just clean? → ElevenLabs v4 or v3 with audio tags, especially for character work or sensitive contexts where a flat delivery undermines the content itself.
- Do you need the widest language or voice library? → ElevenLabs v4 (90+ languages) or v3 (70+).
- Does the data or deployment need to stay inside your own infrastructure? → Deepgram's self-hosted containers, which are an Enterprise offer.
- None of the above bind, and price is the tiebreaker? → Deepgram Aura-2 at $0.030, or ElevenLabs Flash / Turbo at $0.04 if you want ElevenLabs voices, then Cartesia on the Pro plan at $0.05.
Raw API versus a tool that packages the output
Worth separating explicitly: these are developer APIs. You're integrating them into your own product, and you own the plumbing — authentication, streaming, retries, format handling.
If your actual job is producing a finished video rather than building an app, that's a different problem — the one Versely's AI text-to-speech tool is built for. Generate the voiceover and it's already inside the same pipeline as your video, voice cloning, and captions, no file export step between them. Versely's own catalog runs Cartesia Sonic 3.6 at 4 credits per 1,000 characters, Gemini 3.8 Flash TTS and Inworld TTS 2 at 2, Eleven v4 at 7, Eleven v4 Turbo at 4 and ElevenLabs Multilingual at 8, and it doesn't carry Hume or Deepgram — so a project needing one of those as a raw API goes direct to the provider; a voiceover headed into a video is where a packaged tool beats stitching four API accounts together. Live-dubbing a video into another language is where those two conversations meet — see Versely's AI dubbing tool.
For a deeper look at how Versely's own TTS engines compare on language reach, emotion control, and cloning — a related but distinct question from the APIs above — see seven voice engines and how to pick one and latency vs fidelity in voice model choice. If ElevenLabs pricing specifically is the sticking point, ElevenLabs alternatives in 2026 covers that from the workflow-and-cost angle.
FAQ
What's the fastest text-to-speech API in 2026? It depends on how you measure. Cartesia claims first audio in under 90 ms for Sonic 3.6, and ElevenLabs lists about 75 ms for Flash / Turbo. Both figures are the vendors' own, so test on your own stack. That's the metric that matters for real-time voice agents and live dubbing.
Which TTS API sounds the most human? There is no single answer. ElevenLabs positions v4 as its most emotive model, and Cartesia says Sonic is ranked #1 on Artificial Analysis' Speech Arena. Both are vendor claims, so audition your own script on each.
Which TTS API is best for emotional or character voice work? ElevenLabs v4 or v3 with audio tags. Hume Octave 2 was built around emotional fidelity, but Hume's TTS API reached its announced end date on 13 November 2026, so it is no longer an option.
Is there a TTS API for on-prem or enterprise deployment? Deepgram is the pick here: it offers self-hosted containers for Enterprise customers who need to run in their own VPC or on-premise hardware.
What's the cheapest TTS API? Of the ones covered here, Deepgram: Aura-1 at $0.015 and Aura-2 at $0.030 per 1,000 characters pay-as-you-go. ElevenLabs Flash / Turbo is $0.04, Cartesia's Pro plan works out at $0.05 per 1,000 credits, and ElevenLabs v3 is $0.08.
Should I call these APIs directly or use a tool like Versely? Call them directly if you're building your own product around raw TTS — a voice agent, an app feature. Use a packaged tool if the voiceover is headed into a finished video, since it skips the export-and-reimport step between audio and video tools.
The takeaway
There's no single best text-to-speech API in 2026 — there's a best API per constraint. Name your constraint first, then pick: Cartesia or ElevenLabs Flash / Turbo for latency, ElevenLabs v4 or v3 for expressiveness and reach, Deepgram for price and self-hosting. Hume's TTS API has reached its end date, so it is off the list. If the voiceover is bound for a published video rather than your own app, Versely's text-to-speech tool skips the plumbing entirely.
Versely AI Weekly
New AI models, every Thursday.
The image, video, audio and LLM models released that week, what each is good for, and what's new on Versely.